Project Index
Research Projects
My work spans world models for planning and anticipation, action understanding in egocentric and exocentric video, and earlier research in visual and multimodal segmentation.
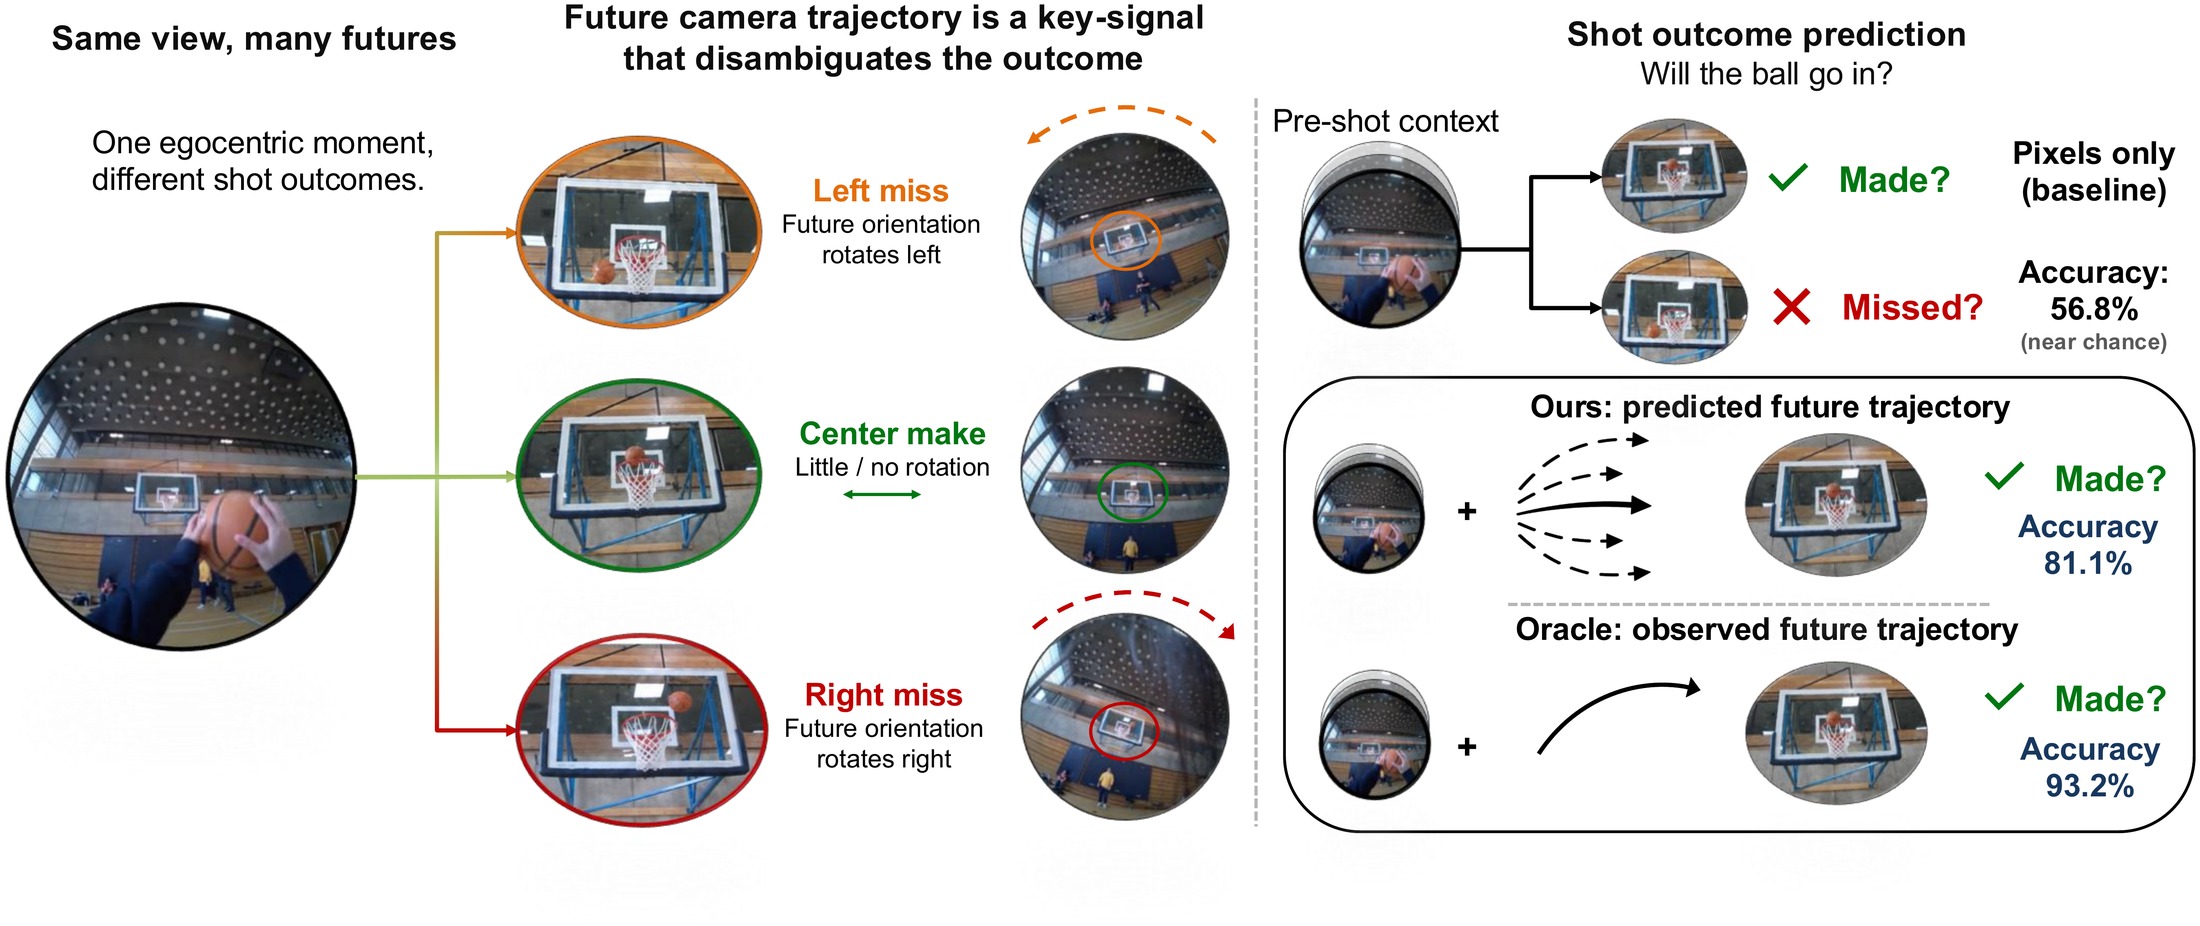
How You Move Tells What You'll Do: Trajectory-Conditioned Egocentric Prediction
TrajPilot predicts possible future camera trajectories from first-person video and uses them to guide action prediction. Motion supplies a fine-grained signal of intent, helping the model plan action sequences and anticipate what someone will do next without observing their future path.
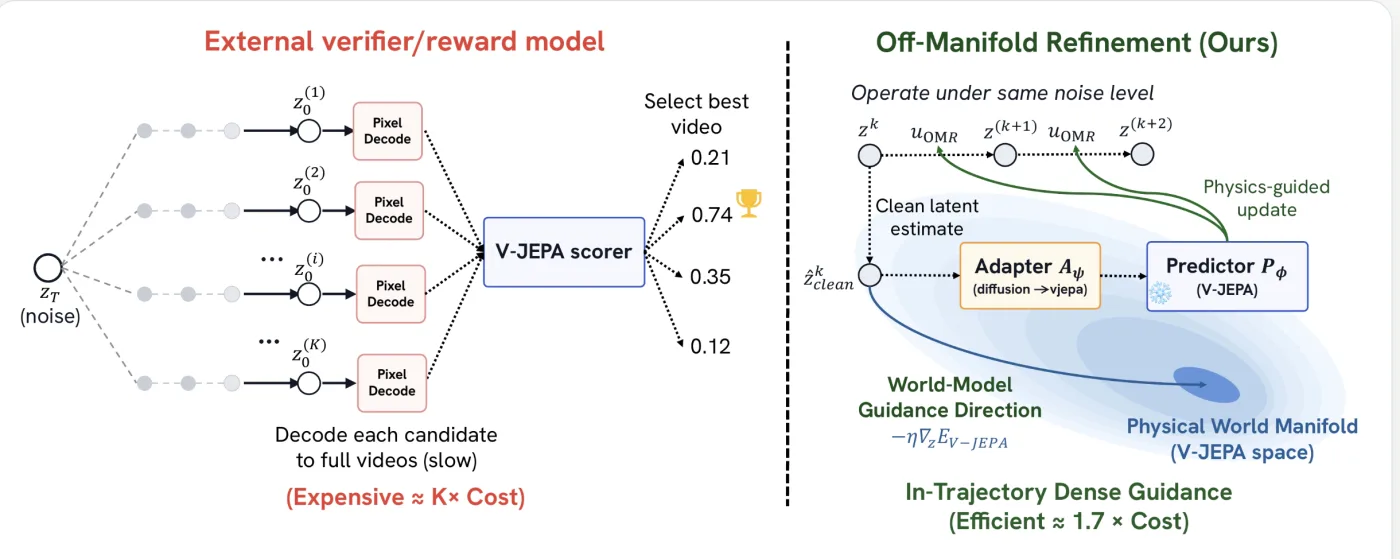
Off-Manifold Refinement: Guiding Video Generators with a Frozen World Model
Video generators can make convincing frames but get the physics wrong. OMR uses a frozen world model to steer a frozen video generator during a single sampling run. A small adapter connects the generator’s intermediate latents to the world model, so it can guide the video before it is finished.
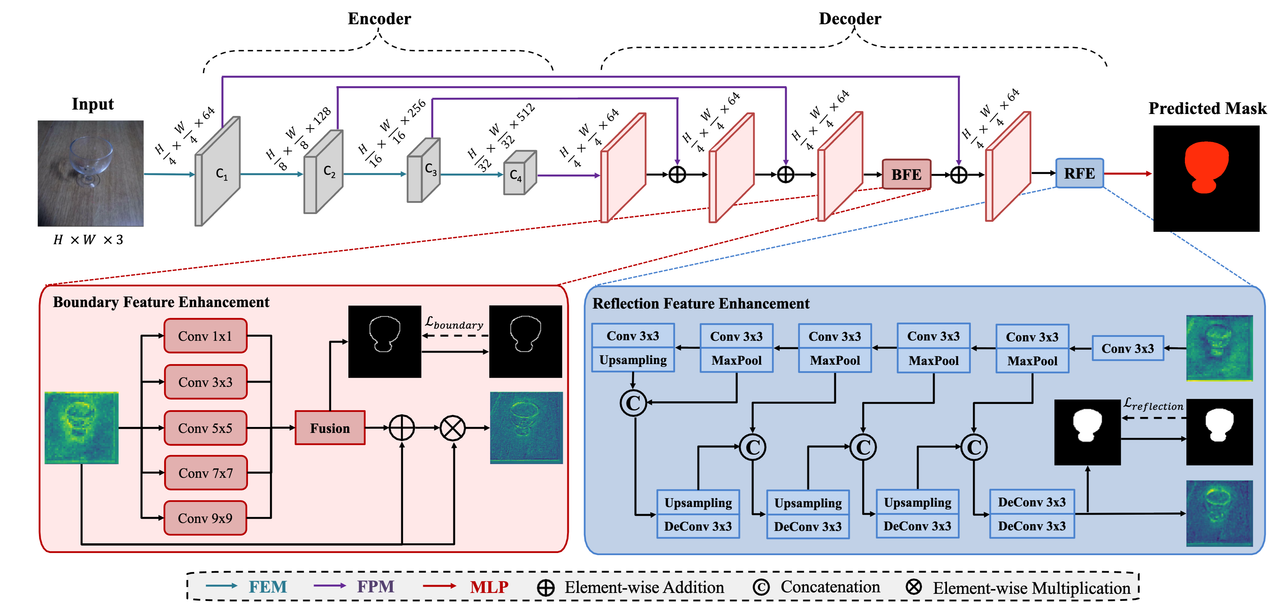
Power of Boundary and Reflection: Semantic Transparent Object Segmentation using Pyramid Vision Transformer with Transparent Cues
TransCues introduces an efficient transformer-based segmentation architecture capable of handling transparent, reflective, and general objects. By proposing Boundary Feature Enhancement (BFE) and Reflection Feature Enhancement (RFE), we enable the model to better capture subtle details in both glass and non-glass regions, resulting in more accurate and robust segmentation.
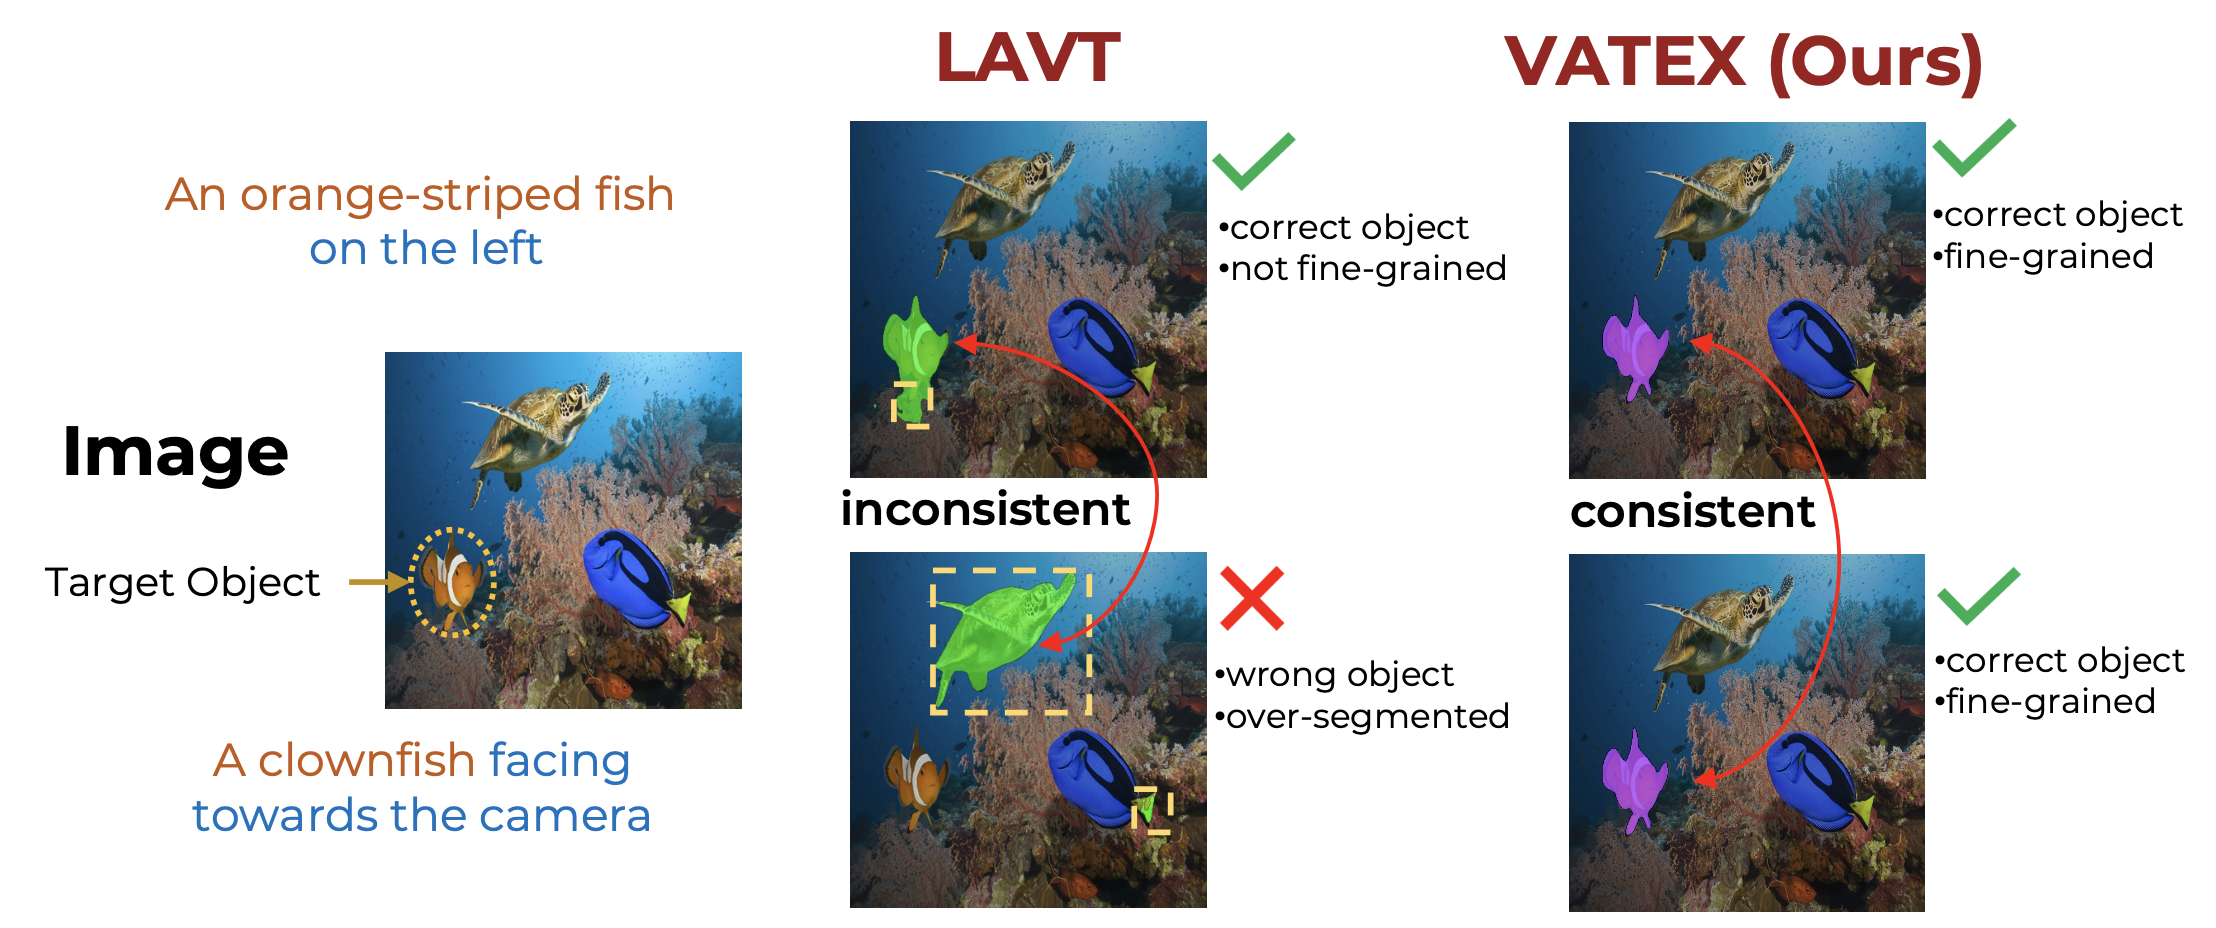
Vision-Aware Text Features in Referring Expression Segmentation: From Object Understanding to Context Understanding
VATEX is a novel method for referring image segmentation that leverages vision-aware text features to improve text understanding. By decomposing language cues into object and context understanding, the model can better localize objects and interpret complex sentences, leading to significant performance gains.
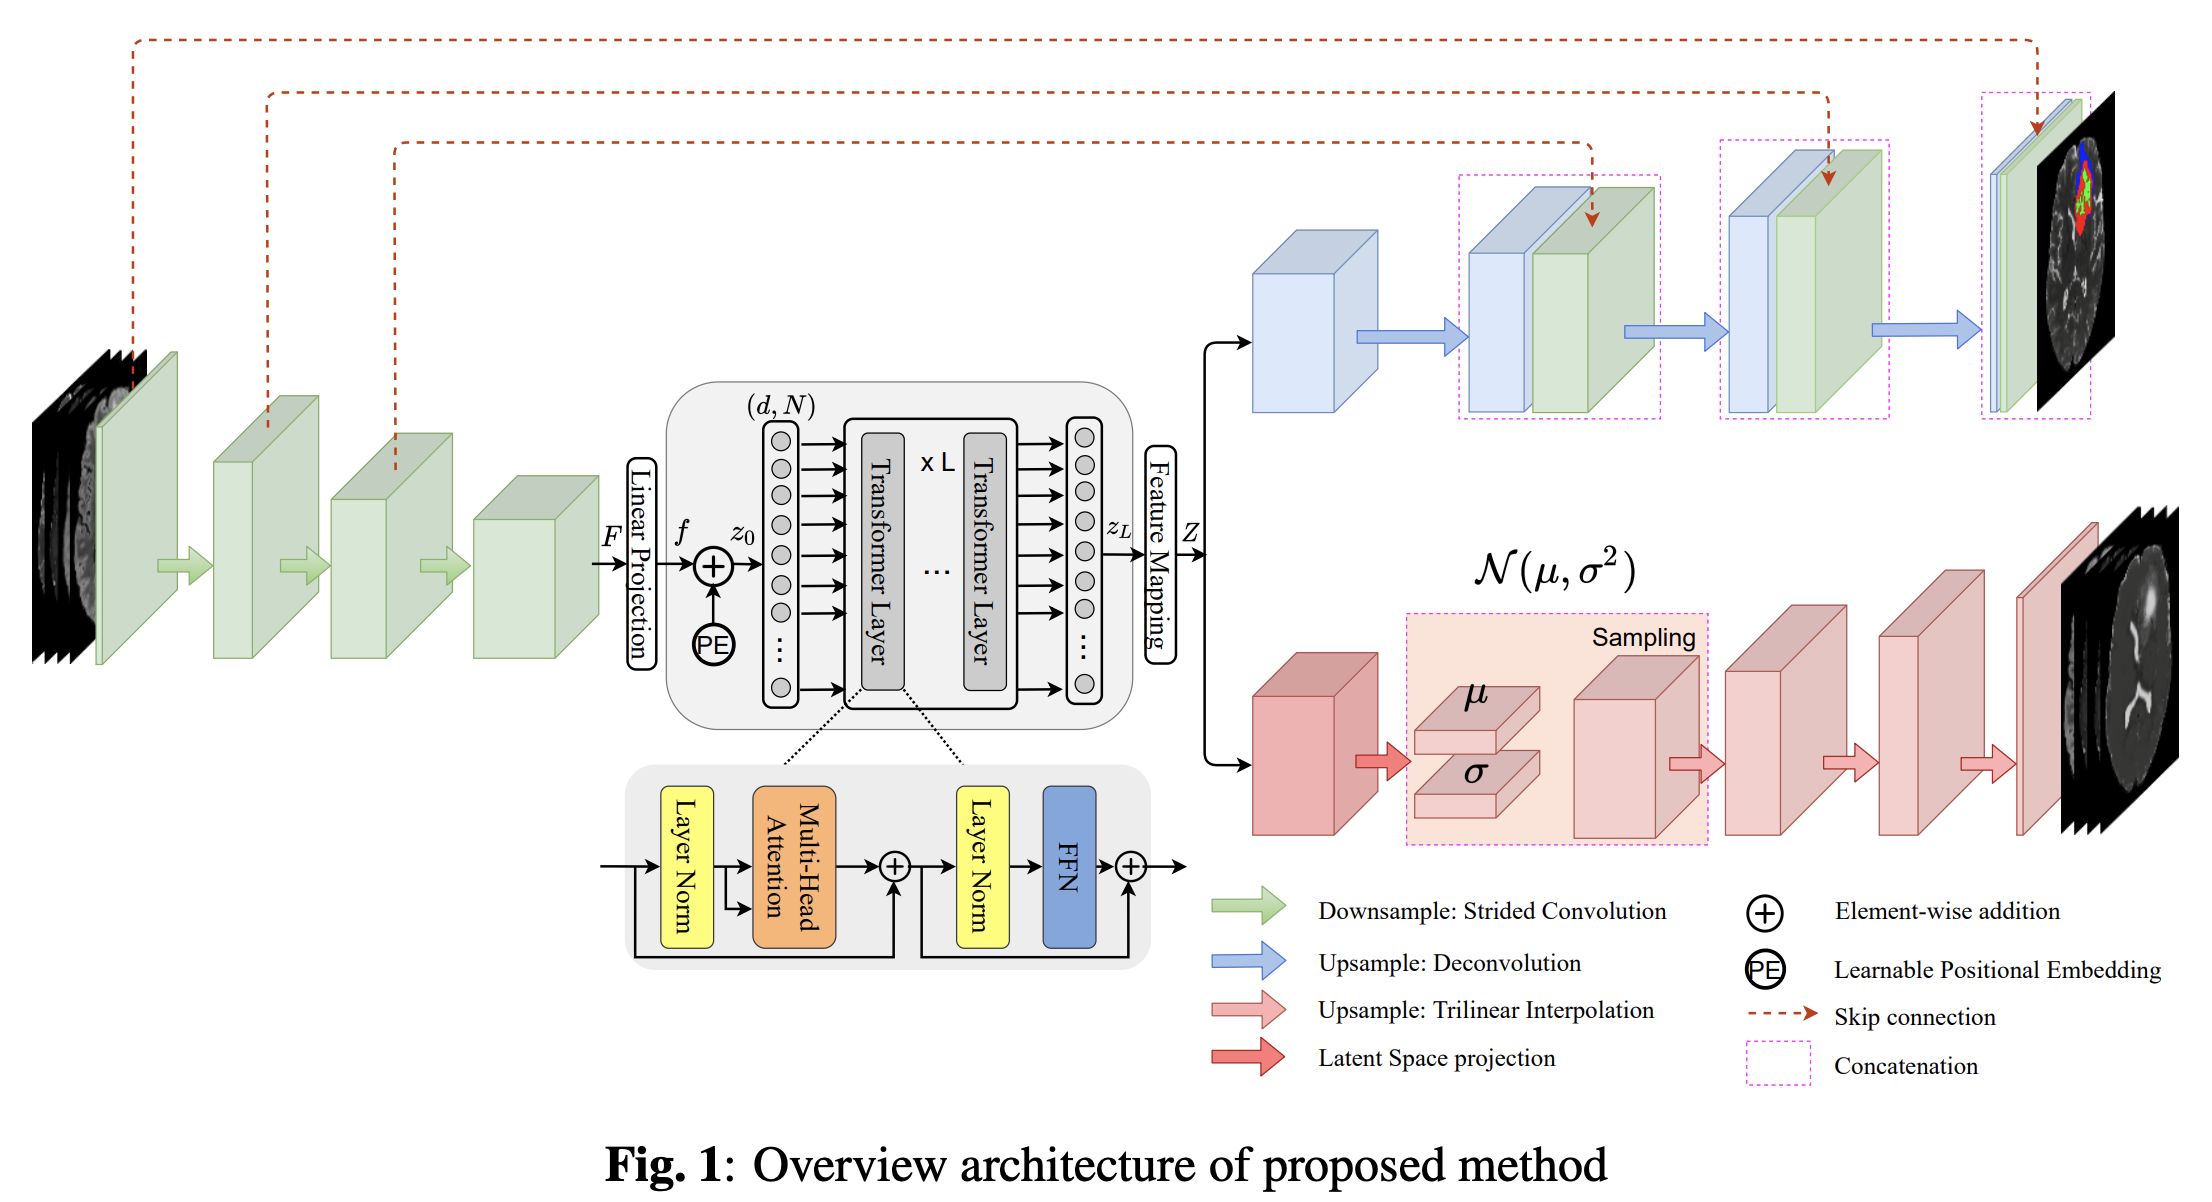
SegTransVAE: Hybrid CNN - Transformer with Regularization for medical image segmentation
SegTransVAE is the first work exploiting the hybrid architecture between CNN, Transformers with the Variational Autoencoder (VAE) branch to the network to reconstruct the input images jointly with segmentation.